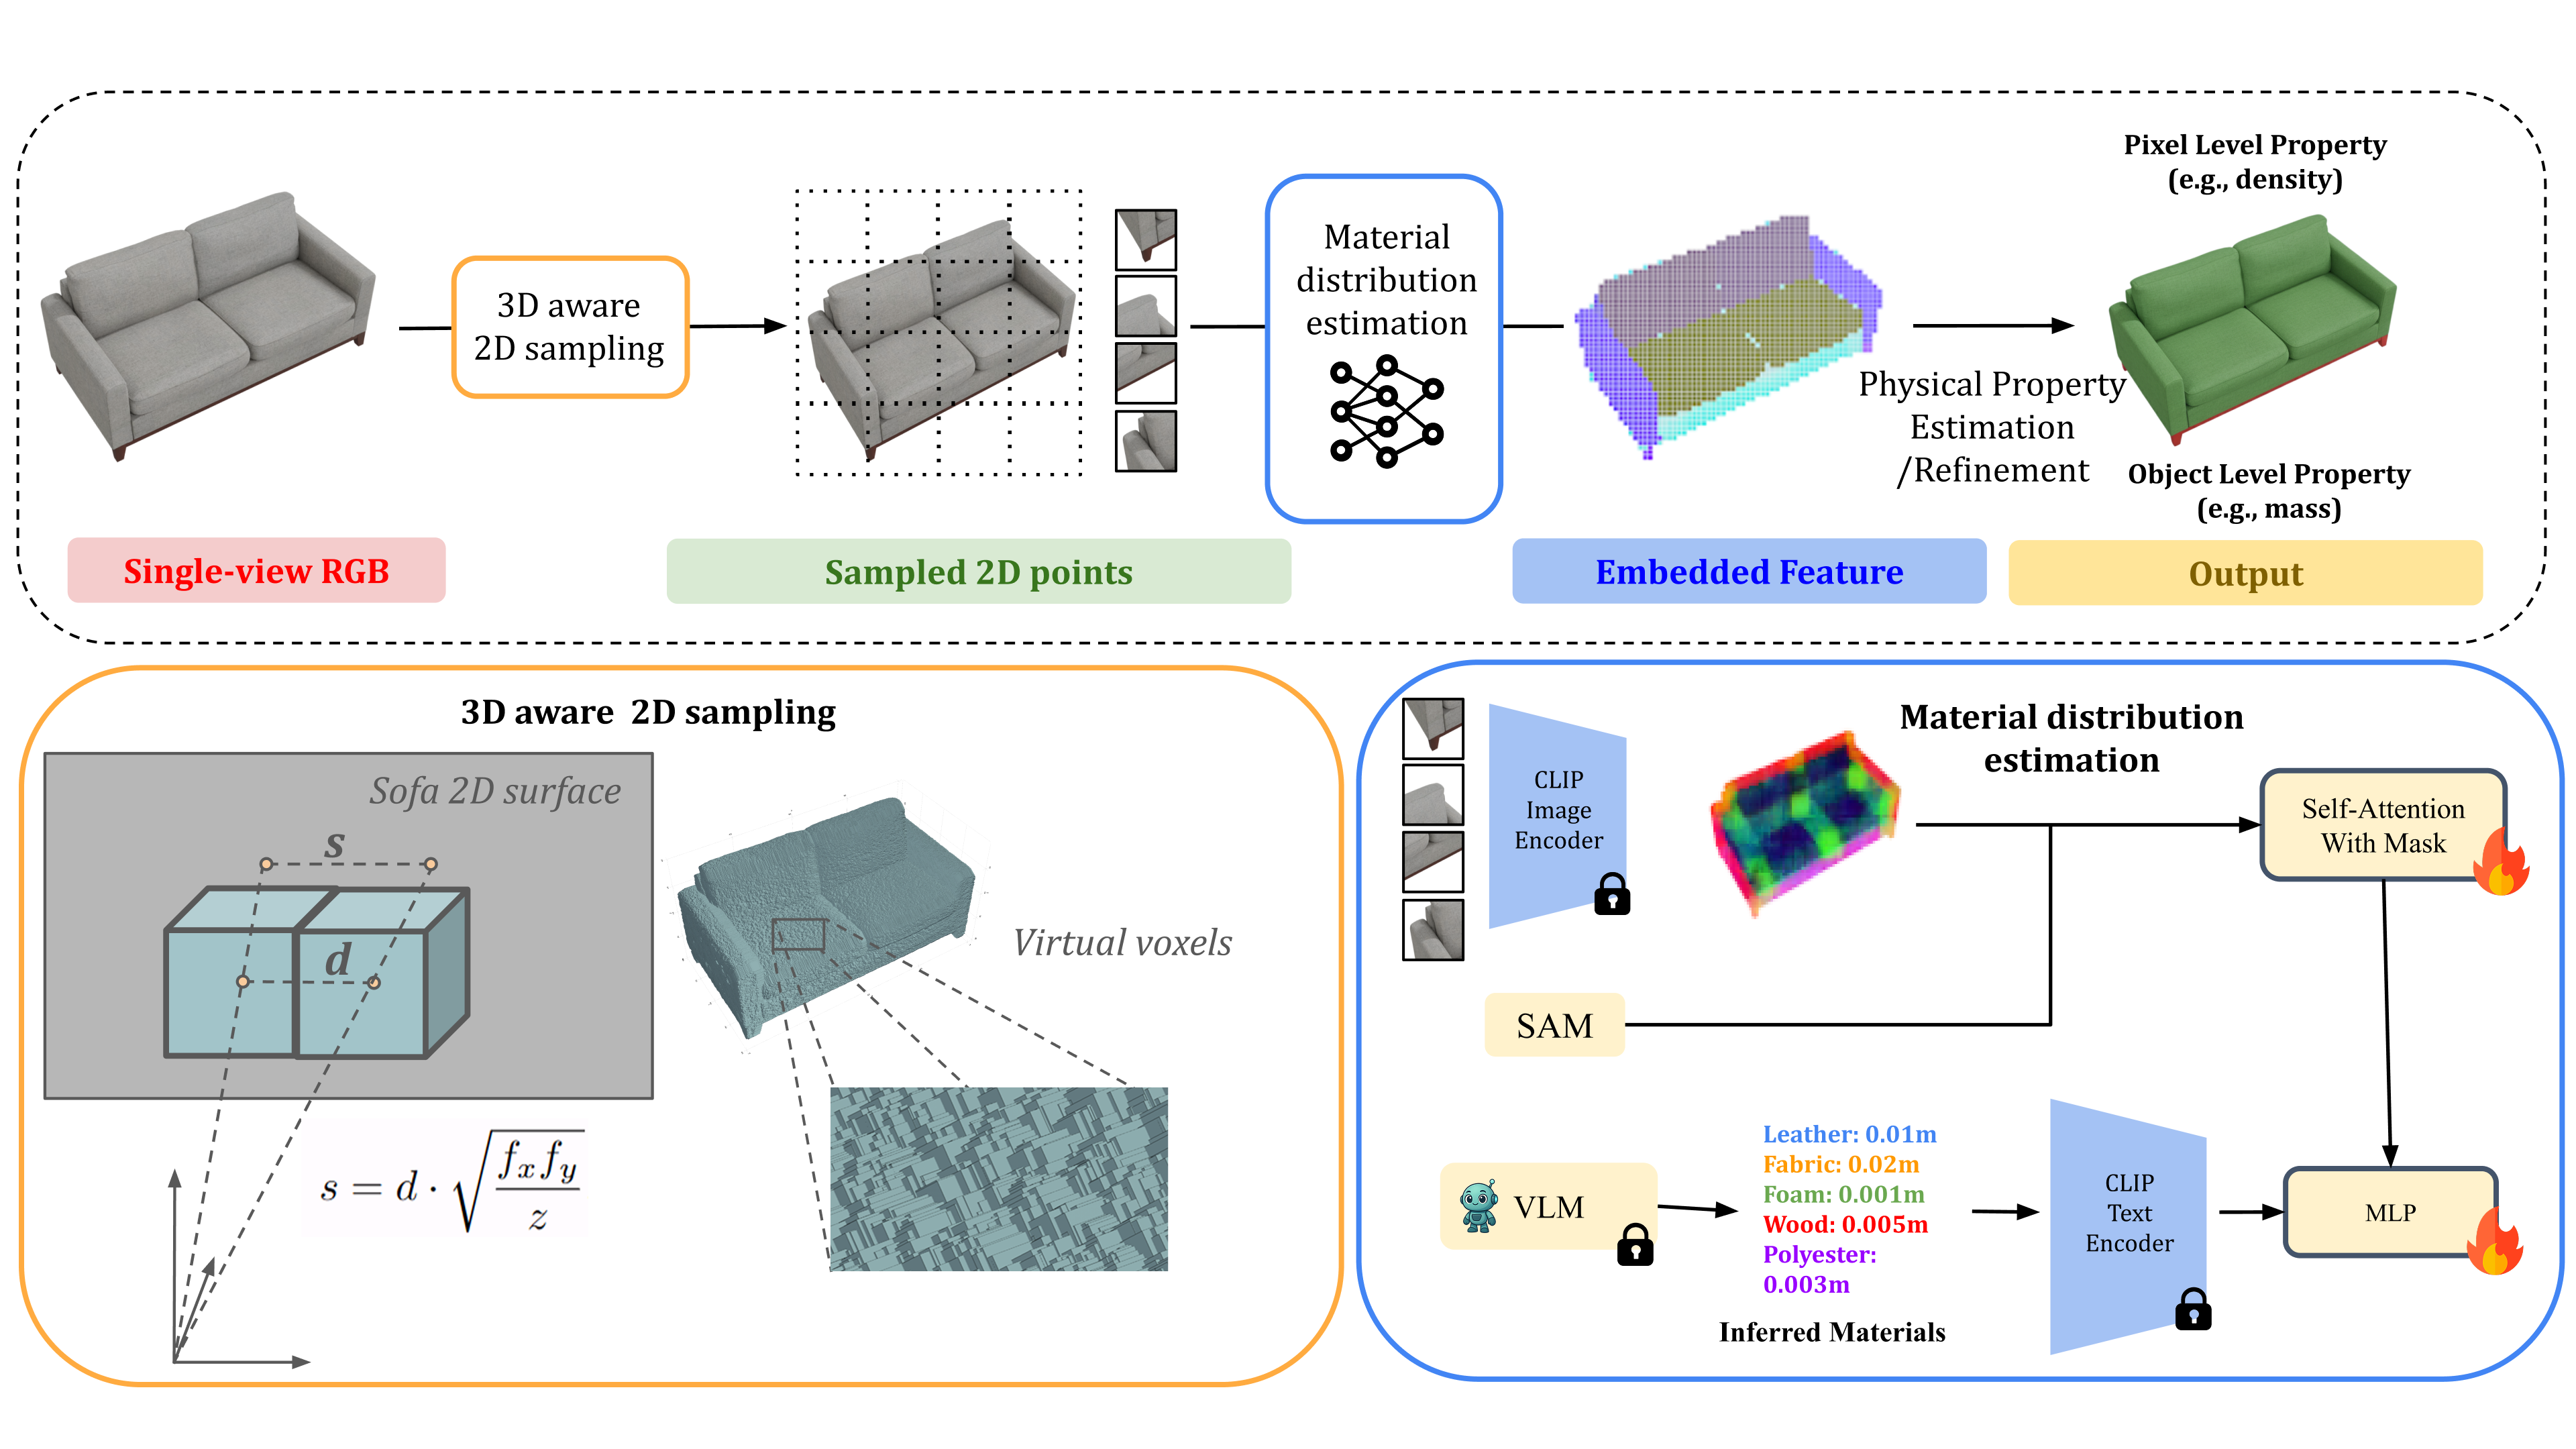
Inferring physical properties such as mass, stiffness, and elasticity from a single image is essential for simulation and embodied AI, yet most existing approaches rely on multi-view reconstruction or physics-based supervision. We introduce SiPhy, a unified framework for single-image physical property reasoning that aligns 3D-aware visual cues, depth with language-based material knowledge. From one RGB image, SiPhy samples pseudo-voxel points, extracts CLIP features, and grounds them to material candidates proposed by an VLM. A part-based contrastive aggregator enforces region consistency, while a heaviness-aware refinement improves thickness and volume estimation for dense objects. Across ABO-500, MVImgNet-100, and PhysXNet-100, SiPhy achieves state-of-the-art single-image performance, surpassing multi-view reconstruction methods by improving mass MnRE by up to 93% (vs. PUGS), reducing density MAE by 35.5% (vs. NeRF2Physics), and lowering Young’s modulus error by 23.5%. We further validate SiPhy on real hand-object interaction datasets, demonstrating its potential as a data annotation engine for physical understanding from single-view imagery.
@inproceedings{le2026siphy,title={SiPhy: Single-Image Physical Property Reasoning},author={Le, Hoang and Kwon, Joonwoo and Ismayilzada, Elkhan and Zhang, Yufei and Cui, Zijun},booktitle={Proceedings of the European Conference on Computer Vision (ECCV)},year={2026},note={Main track. arXiv and ECCV links coming soon.},}
in progress
FunctionalGrasp: Part-Aware Functional Maps for Cross-Category Generalizable Robotic Grasping from a Single Demonstration
Exploring how to transfer a single human grasp demonstration to a robotic dexterous hand across object categories using part-aware functional correspondences. The goal is to enable generalizable, contact-rich robotic grasping from just one demonstration.
@unpublished{le2026functionalgrasp,title={FunctionalGrasp: Part-Aware Functional Maps for Cross-Category Generalizable Robotic Grasping from a Single Demonstration},author={},year={2026},note={Ongoing work at UGRIP.},}
2024
MidSURE
DAM3D: Detect Anything in 3D
Hoang Le, Abhinav Kumar, Shengjie Zhu, and 1 more author
2024
Poster presented at MidSURE 2024, Michigan State University.
A unified inference pipeline for monocular 3D object detection combining SAM, metric depth estimation, and FoundationPose. Sustains 18 FPS on an RTX 3090 (a +44% throughput improvement over Mask R-CNN) and achieves +3% AP3D over the prior state of the art on ScanNet. Work with Dr. Abhinav Kumar and Dr. Xiaoming Liu at the MSU CV Lab.
@misc{le2024dam3d,title={DAM3D: Detect Anything in 3D},author={Le, Hoang and Kumar, Abhinav and Zhu, Shengjie and Liu, Xiaoming},year={2024},note={Poster presented at MidSURE 2024, Michigan State University.},}